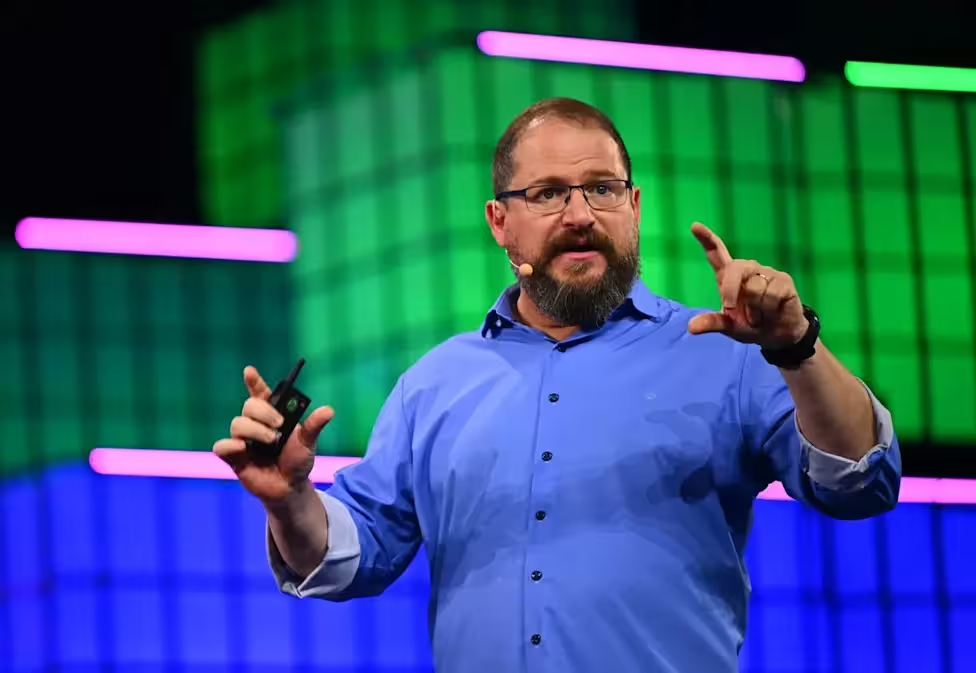
Qualcomm CEO Cristiano Amon said some AI companies are building smartphones that could run 100-billion-parameter language models continuously by 2028.
Amon made the comment in an interview with Fireside Alpha on October 10, 2026 and declined to name the companies involved.
Running a 100-billion-parameter model on a phone faces major memory constraints. A 4-bit quantized 100B model requires roughly 50 gigabytes of RAM, and a 2-bit variant would still need about 25 gigabytes solely for the model, before accounting for the operating system, apps, and context cache.
Qualcomm and others cite DRAM supply and cost as the biggest barriers. The company said the industry is unlikely to cross a common 16 gigabyte memory threshold soon, and manufacturers have trimmed higher-RAM variants amid tight DRAM markets, despite Android phones offering up to 24GB LPDDR5X about a year ago.
Continuous inference on denser models also increases heat and risks thermal throttling, which remains a practical limit even if raw memory were available.
Chipset packaging changes, including Apple’s A20 Pro and Qualcomm’s Snapdragon 8 Elite Extreme Gen 6, address some integration issues but do not eliminate the memory bottleneck.
Technical workarounds include aggressive quantization, which sharply reduces memory needs; 1-bit variants can fit in DRAM but model quality, especially for reasoning, degrades significantly beyond 4-bit quantization according to industry assessments.
Another approach is Mixture of Experts with expert offloading, where only a subset of experts is active in RAM per token and the remainder stay on flash storage. Apple has researched running models from onboard flash, but UFS and NVMe storage remain slower than DRAM and can reduce inference speeds.
Model distillation is the more marketable path for now: distilled 20B to 30B models can approximate the performance of some 100B models on-device while keeping memory and thermal requirements manageable.
Amon did not provide a technical roadmap or identify partners. DRAM supply, cost, and thermal limits remain the key constraints to running 100B models natively on smartphones by 2028.
“I cover emerging technologies, digital innovation, and the intersection of tech and everyday life. My goal is to make complex trends accessible and inspiring.”

Discussion
Leave a Comment
Comments
No comments yet. Be the first.